Disaster Recovery Business ContinuityDisaster RecoveryRPORTO

Article & Tutorial

RPO vs RTO Explained: Backup and Disaster Recovery Examples

Understand recovery point objective and recovery time objective with practical examples, measurement methods, technology choices, dependencies, and recovery testing.

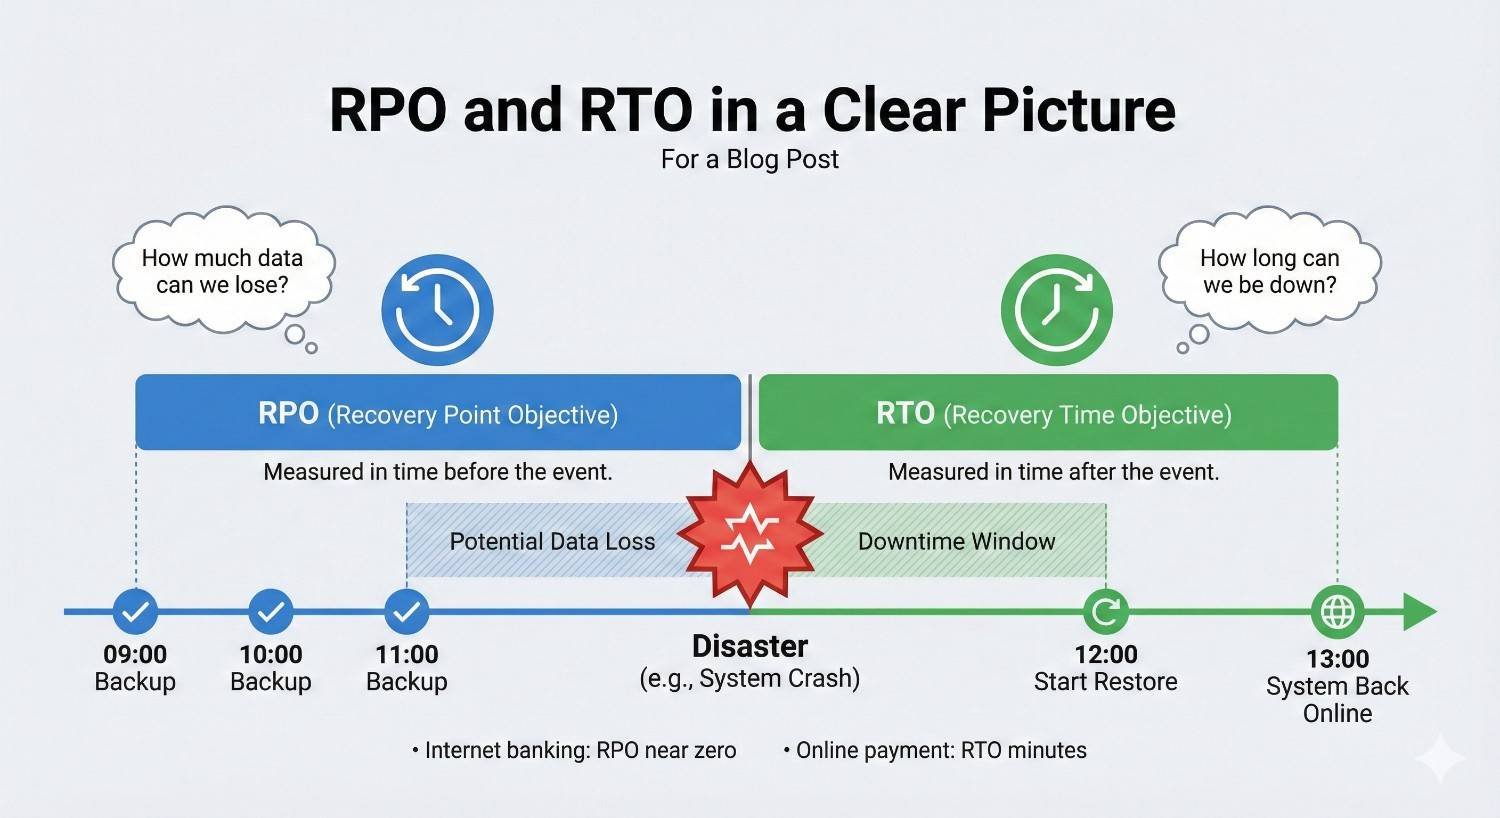
RPO and RTO disaster recovery timeline comparison
Contents

Recovery point objective (RPO) and recovery time objective (RTO) turn business impact into measurable recovery targets. RPO defines how much recent data loss is acceptable, measured backward in time. RTO defines how quickly a service must be restored after disruption.

RPO and RTO answer different questions

MetricBusiness questionPrimary design influence
RPOHow much data can we afford to lose?Backup and replication frequency
RTOHow long can the service be unavailable?Recovery architecture, staffing, and automation

RPO example

If an order system has a 15-minute RPO and fails at 14:00, the organization accepts at most 15 minutes of lost transactions. Nightly backups cannot meet that target; frequent snapshots, log shipping, or continuous replication may be required.

RTO example

If the same system has a two-hour RTO, the service and its required dependencies must be restored within two hours of the declared incident. That window includes assessment, infrastructure recovery, data restoration, validation, network changes, and business handoff.

Targets must come from business impact

  • Revenue and contractual impact of downtime.
  • Safety, privacy, and regulatory obligations.
  • Volume and value of transactions created over time.
  • Operational workarounds available during an outage.
  • Upstream and downstream system dependencies.
  • Cost of the technology and staffing needed to meet the objective.

Map technology to the objective

Target profileTypical approach
Long RPO and RTOPeriodic backups with manual restoration
Short RPO, moderate RTOFrequent snapshots or replication with planned recovery
Near-zero RPO, short RTOSynchronous or continuous replication and automated failover
Critical serviceMulti-site design, rehearsed failover, and dependency resilience

Backups are not the whole recovery plan

A backup may protect data but not restore identity, DNS, networking, secrets, certificates, application configuration, or third-party access. Define recovery order, owners, credentials, clean-room procedures, validation criteria, and communication steps.

Test and measure actual recovery

  1. Restore data to an isolated environment.
  2. Record the real recovery point achieved.
  3. Time every recovery stage, including approvals and validation.
  4. Confirm application integrity with business owners.
  5. Document gaps and repeat the exercise after remediation.

Objectives are promises; achieved recovery metrics are evidence. Review both whenever services, data volumes, dependencies, or business tolerance change.

NIST contingency planning guidance

Did this help?

Yes No

Join the discussion

0 Comments

Ask questions, add context, or share what worked.

Sign in to join the discussion

No comments yet. Start the discussion.

More from Melochip Editorial

Related articles

Stay in the loop. Get new Melochip articles

Receive Melochip article updates when new articles are available. Explicit opt-in only.

No pre-checked boxes. Unsubscribe support is part of the subscriber foundation.