
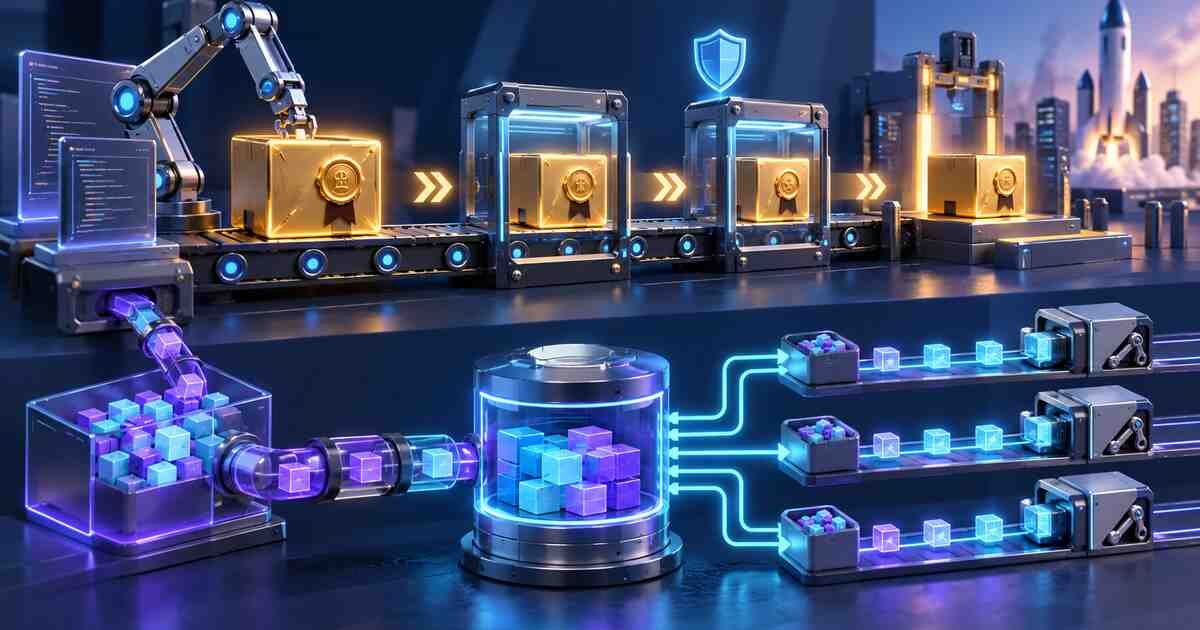
Artifacts and cache solve different pipeline problems. Artifacts preserve job outputs for later jobs, reports, downloads, or deployments. Cache reuses dependency data to reduce repeated downloads or computation. A pipeline often uses both, but never for the same purpose.
Quick comparison
| Characteristic | Artifacts | Cache |
|---|---|---|
| Primary purpose | Preserve outputs and reports | Reuse dependencies or intermediate reusable data |
| Typical examples | Packages, binaries, test reports, logs | Package-manager downloads, compiler cache |
| Reliability expectation | Required output for downstream work | Performance optimization that may be missing |
| Retention | Explicit expiry and project storage | Cache policy and backend lifecycle |
| Security concern | Sensitive output and download access | Cache poisoning and cross-branch reuse |
Use artifacts for required outputs
If a downstream job must consume exactly what an upstream job produced, use artifacts or an artifact repository. Preserve immutable packages, test reports, coverage data, and deployment manifests with appropriate expiry and access controls.
Use cache for acceleration
Cache package-manager downloads or compiler state that can be regenerated safely. A job should still work when the cache is empty. Choose keys that prevent incompatible branches, architectures, lock files, or tool versions from sharing data.
A common combined pattern
- Restore a dependency cache using a lock-file-based key.
- Install dependencies and update the cache if policy allows.
- Build the application.
- Publish the build output as an artifact.
- Download that artifact in test or deployment jobs.
- Promote release packages to a durable repository when needed.
Security controls
- Do not cache credentials or decrypted secret files.
- Separate protected and untrusted branch caches.
- Avoid executable cache content from unknown pipelines.
- Set artifact access and expiry deliberately.
- Scan release artifacts and preserve checksums.
- Do not treat short-lived job artifacts as a permanent release repository.
Performance diagnosis
Measure download time, archive creation, extraction, cache hit rate, artifact size, and storage growth. A cache can slow a pipeline when large archives are uploaded and downloaded even though dependencies change frequently.
The rule is simple: artifacts carry required results forward; cache makes repeatable preparation faster. If losing the data would make the pipeline incorrect, it should not exist only in cache.
Join the discussion
0 CommentsAsk questions, add context, or share what worked.
More from Melochip Editorial

Learn what Playwright testing is, why modern QA teams use it, how testers can get started, and the major types...
7 min read · Sep 19, 2026

Learn how Kubernetes Deployments and ReplicaSets work with practical YAML, scaling, self-healing, rolling upda...
7 min read · Sep 17, 2026

Learn Kubernetes security best practices with RBAC, Secrets, ServiceAccounts, Pod securityContext, NetworkPoli...
6 min read · Sep 17, 2026Related articles
Learn how Kubernetes Deployments and ReplicaSets work with practical YAML, scaling, self-healing, rolling upda...
7 min read · Sep 17, 2026

Learn Kubernetes monitoring and logs with kubectl logs, events, metrics-server, top commands, Prometheus, Graf...
5 min read · Sep 17, 2026
Learn Kubernetes Ingress with controllers, IngressClass, host and path routing, TLS, DNS, annotations, redirec...
8 min read · Sep 17, 2026

Learn Kubernetes ConfigMaps and Secrets with YAML, environment variables, file mounts, update behavior, immuta...
8 min read · Sep 17, 2026Stay in the loop. Get new Melochip articles
Receive Melochip article updates when new articles are available. Explicit opt-in only.
No comments yet. Start the discussion.