
Databases Database ArchitectureMongoDBMySQLPostgreSQL

Article & Tutorial

MySQL vs PostgreSQL vs MongoDB: Choosing a Database

Compare MySQL, PostgreSQL, and MongoDB by data model, transactions, queries, scaling, operations, and workload fit, with guidance for choosing a primary database.

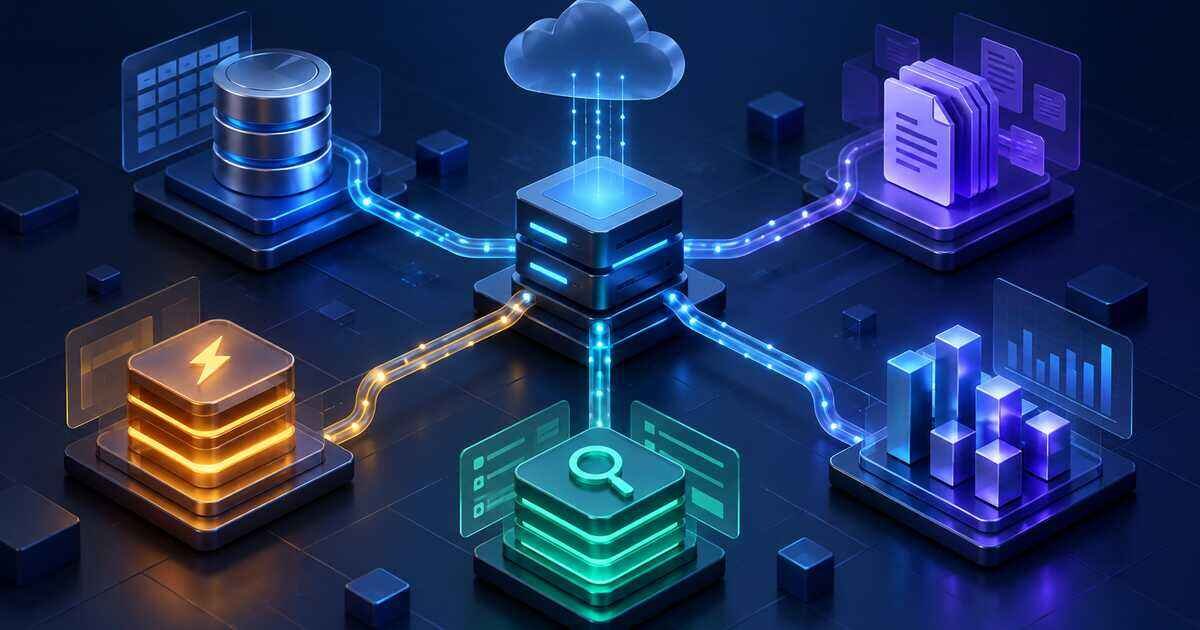
Relational, document, cache, search, and analytics database architecture
Contents

Database selection should begin with data integrity, query patterns, operational capability, and growth expectations—not popularity. MySQL and PostgreSQL are relational systems with strong SQL ecosystems. MongoDB is a document database that stores records in flexible BSON documents.

Quick comparison

DatabaseStrongest fitWatch for
PostgreSQLComplex relational workloads, rich SQL, extensions, strict constraintsOperational tuning and disciplined schema design
MySQLWidely hosted web workloads and familiar relational operationsFeature and behavior differences across versions and engines
MongoDBDocument-shaped data and rapidly evolving record structuresSchema governance, relationship handling, and query-driven modeling

Data model comes first

Choose a relational database when relationships, constraints, joins, and multi-row transactions are central to correctness. Choose a document model when an aggregate naturally lives as one document and is usually read or written together. Flexible schema is not the absence of schema; applications still need validation and compatibility rules.

Transactions and consistency

All three platforms support important transactional capabilities, but the simplest reliable design is often the one that keeps related changes within a natural transaction boundary. Confirm isolation behavior, failure semantics, replication guarantees, and rollback needs under the exact deployment model.

Query and indexing patterns

  • List the highest-volume reads and writes before selecting technology.
  • Test joins, aggregations, text search, and JSON access with production-shaped data.
  • Create indexes from observed query plans, not guesses.
  • Measure write amplification and index storage.
  • Plan data retention and archival before tables or collections become large.

Scaling and operations

Read replicas, partitioning, sharding, caching, and managed services can extend capacity, but each adds operational complexity. Backup restoration, point-in-time recovery, upgrades, observability, access control, and staff experience matter as much as benchmark throughput.

Use specialized systems deliberately

A primary transactional database can be combined with Redis for caching, a search engine for full-text retrieval, or a columnar warehouse for analytics. Avoid adding a second data system unless its benefit justifies synchronization, consistency, security, and recovery work.

A practical selection method

  1. Document integrity and availability requirements.
  2. Model representative entities and relationships.
  3. Implement the hardest queries and write paths.
  4. Load test with realistic concurrency and data volume.
  5. Run backup, restore, failover, and upgrade exercises.
  6. Select the option the team can operate safely for years.

PostgreSQL is a strong general default for many applications, MySQL remains an excellent broadly supported relational choice, and MongoDB is effective when document aggregates align with access patterns. The workload and operating model should make the final decision.

Did this help?

Yes No

Join the discussion

0 Comments

Ask questions, add context, or share what worked.

Sign in to join the discussion

No comments yet. Start the discussion.

More from Melochip Editorial

Related articles

Stay in the loop. Get new Melochip articles

Receive Melochip article updates when new articles are available. Explicit opt-in only.

No pre-checked boxes. Unsubscribe support is part of the subscriber foundation.



